Character Consistency Invideo Agent: Flawless AI Video Generation Tactics
Creating professional videos using artificial intelligence presents a massive creative challenge. The technology generates stunning visuals effortlessly. However, maintaining a […]
Creating professional videos using artificial intelligence presents a massive creative challenge. The technology generates stunning visuals effortlessly. However, maintaining a stable visual identity across multiple scenes proves incredibly difficult. Therefore, creators constantly struggle with morphing faces and shifting wardrobes. This is exactly why achieving character consistency Invideo agent results revolutionizes production workflows. This powerful AI platform anchors digital identities firmly throughout entire video projects. Furthermore, it eliminates the frustrating visual drift that plagues most text-to-video platforms. Consequently, filmmakers produce cohesive narratives without manual correction overhead. In this comprehensive guide, we will explore advanced tactics to lock visual identity perfectly. Ultimately, mastering these strategies guarantees flawless, professional AI video generation.
Character Consistency Invideo Agent: Solving AI Video Generation Flaws
Generative algorithms thrive on creative variation. However, this inherent randomness destroys narrative continuity quickly. A protagonist might change hair color between shots. Therefore, viewers immediately notice the artificial nature of the production. The Invideo agent directly tackles this systemic flaw using sophisticated identity anchoring mechanisms. It references a locked state throughout the rendering pipeline. Furthermore, it overrides the latent space diffusion process to maintain specific traits. Consequently, your digital actor remains perfectly stable from the first frame to the closing credits.
The Morphing Nightmare in Text-to-Video Production
Standard text-to-video models treat every prompt as an isolated request. Therefore, they generate a new interpretation of your character for every single scene. The model ignores previous context entirely. If you prompt a woman in a red dress, the next scene might show her in blue. Furthermore, facial structures shift subtly as the algorithm improvises new pixels. These inconsistencies shatter audience immersion completely. Viewers distrust videos where the lead actor morphs into a stranger. Therefore, traditional AI video generation fails for structured storytelling. The Invideo agent resolves this nightmare by enforcing strict continuity constraints.
How AI Agents Anchor Visual Identity
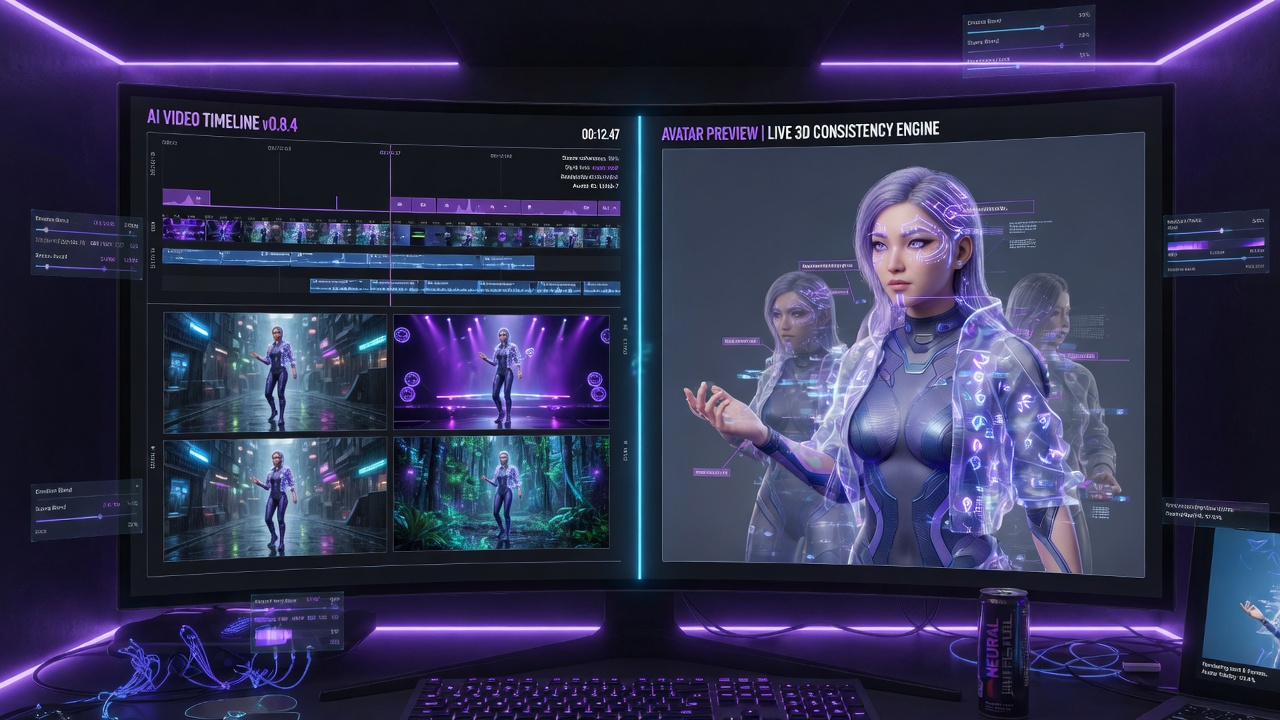
The agent functions as an intelligent director supervising the generative process. It does not merely generate random frames. Instead, it maps a persistent feature vector to your specified character. This vector encodes facial geometry, skin tone, and clothing details precisely. When the model renders a new scene, the agent injects this reference vector forcefully. Furthermore, it applies attention masks to prioritize identity preservation over artistic extrapolation. The algorithm sacrifices random variation to maintain strict adherence to your original design. Consequently, the generated output conforms to your established visual reality. As a result, your digital human remains reliably recognizable across diverse environments. Ultimately, intelligent agent supervision overrides chaotic diffusion defaults.
Core Mechanics of the Invideo Agent for Digital Avatars
Understanding the underlying architecture helps creators leverage the platform effectively. The system utilizes multiple overlapping processes to lock identity. These mechanisms work together to prevent visual drift. Therefore, relying on the agent provides superior stability compared to basic prompting. It combines reference parsing, feature extraction, and guided diffusion seamlessly.
Maintaining Facial Landmarks Across Scenes
The human eye detects incredibly subtle facial variations. Therefore, even minor shifts in eye spacing or nose shape ruin character consistency. The Invideo agent utilizes advanced facial landmark detection algorithms. It maps critical facial topology during the initial reference parsing phase. These landmarks act as immutable anchor points during the generation process. When the algorithm synthesizes new dialogue or expressions, it strictly adheres to this underlying geometry. Furthermore, it prevents temporal smoothing from inadvertently altering bone structure over time. Consequently, your digital avatar maintains its exact structural identity regardless of emotional changes. As a result, emotional performances feel authentic and visually stable. Ultimately, landmark preservation guarantees facial integrity across infinite frames.
Wardrobe and Styling Preservation Algorithms
Clothing consistency matters just as much as facial stability. A corporate spokesperson cannot suddenly change suits mid-sentence. Therefore, the agent implements rigorous styling preservation algorithms. It segments the character from the background and locks specific pixel regions. The system categorizes clothing items, accessories, and color palettes distinctly. When generating new actions, the diffusion model references these locked segmentation maps. Furthermore, the agent prevents style bleeding where background colors contaminate the character’s wardrobe. Consequently, your subject retains their exact professional appearance throughout the entire presentation. As a result, your brand identity remains visually uncompromised. Ultimately, styling algorithms prevent distracting wardrobe malfunctions.
Tactics to Achieve Flawless Character Consistency
The platform provides powerful tools, but users must apply strategic workflows. Therefore, merely typing basic prompts yields suboptimal results. You must feed the agent high-quality data and precise instructions. Implementing specific tactics maximizes the identity locking potential of the system. Consequently, your outputs achieve professional broadcast standards reliably.
Defining Robust Reference Images
The entire consistency framework relies on your initial input. Therefore, uploading a vague or poorly lit reference image guarantees failure. You must provide the agent with a pristine, high-resolution anchor photo. Ensure the face features even, shadowless illumination. Furthermore, the subject should look directly at the camera to capture symmetrical geometry. Avoid images with heavy occlusion from sunglasses or hats. The agent extracts its baseline vector from this exact source. Consequently, a superior reference image generates a superior identity lock. As a result, the algorithm performs confidently with accurate foundational data. Ultimately, garbage in strictly produces garbage out, even with advanced agents.
Utilizing Specific Prompting Parameters
Vague language confuses generative models terribly. Therefore, you must describe your character with exhaustive specificity. Define their exact age, ethnicity, and hair texture explicitly. Furthermore, detail their clothing materials and colors precisely. Instead of prompting a man in a suit, prompt a forty-year-old man with dark curly hair wearing a navy blue tailored wool suit. The Invideo agent uses this textual embedding to reinforce the visual reference vector. It cross-references the text description with the uploaded image continuously. Consequently, the system possesses dual reinforcement anchors preventing visual drift. As a result, your character manifests exactly as you envisioned. Ultimately, precise language eliminates destructive algorithmic ambiguity.
Locking Seed Values for Reproducibility
Generative algorithms rely on random noise seeds to initiate creation. Therefore, changing the seed produces an entirely different output each time. However, the Invideo agent allows users to lock specific seed values. By maintaining a constant seed, you force the model to start from the exact same latent noise pattern. This technique dramatically enhances reproducibility across multiple generation runs. Furthermore, locked seeds ensure that background elements and lighting remain consistent when you generate new dialogue lines. Consequently, you can seamlessly splice different generated clips together without jarring visual shifts. As a result, your editing workflow becomes incredibly fluid and predictable. Ultimately, seed locking provides mathematical certainty in an otherwise random process.
Overcoming Common AI Video Generation Challenges
Even with advanced agents, specific scenarios test consistency limits. Complex movements and lighting changes stress the identity preservation algorithms. Therefore, anticipating these challenges allows creators to design around them. Implementing preventative measures ensures your production survives difficult sequences.
Preventing Background Bleed into Characters
AI models sometimes confuse foreground and background elements. Therefore, complex backgrounds occasionally bleed into the character’s outline. A character standing before a busy pattern might absorb those shapes into their clothing. The Invideo agent employs sophisticated foreground segmentation to prevent this artifact. However, extremely chaotic backgrounds can still overwhelm the system. Therefore, place your characters against relatively clean, contrasting backgrounds whenever possible. Use shallow depth of field effects to blur distracting background details. Consequently, the agent isolates your subject cleanly without environmental contamination. As a result, your character retains their distinct boundaries perfectly. Ultimately, simple environments facilitate cleaner subject isolation.
Managing Lighting Variations and Shadows
Dynamic lighting significantly alters facial appearance. Therefore, moving a character from an indoor office to outdoor sunlight risks consistency failures. Shadows can obscure the facial landmarks the agent relies upon. Furthermore, color temperature shifts change apparent skin tones drastically. To mitigate this, describe the intended lighting explicitly in your prompts. Guide the agent to maintain consistent ambient illumination across scene transitions. Furthermore, request fill lighting to soften harsh shadows that disrupt facial geometry. Consequently, the model adapts the character smoothly to new environments without losing core identity. As a result, your narrative transitions feel natural and visually cohesive. Ultimately, proactive lighting management prevents accidental identity distortion.
Handling Complex Physical Movements
Rapid motion forces the algorithm to interpolate heavily between frames. Therefore, fast action sequences often degrade facial structure temporarily. A character turning their head quickly might lose their nose for a single frame. The Invideo agent utilizes advanced temporal interpolation models to combat this. However, extremely rapid movements still challenge the system. Therefore, constrain your digital actors to measured, deliberate gestures. Avoid fast whip pans or complex gymnastic routines that stretch physical plausibility. Consequently, the agent maintains structural integrity during moderate motion profiles. As a result, your videos avoid the uncanny valley artifacts common in fast AI motion. Ultimately, controlled choreography preserves facial fidelity.
The Invideo Agent Workflow for Scalable Video Production
Professional creators produce long-form content requiring hundreds of consistent shots. Therefore, a reliable workflow must scale beyond isolated single-generation tests. The Invideo agent provides project-level management features to support massive productions. You establish characters once and deploy them across entire campaigns. Consequently, you build a reusable digital asset library efficiently.
Storyboarding with Persistent Identities
Effective video production begins with a structured storyboard. Therefore, you must plan your scenes before generating any footage. The agent allows you to assign persistent identity profiles to specific roles in your project. You define the protagonist once within the project dashboard. Then, you simply select this profile whenever you generate a new scene featuring that character. The agent automatically applies the appropriate reference vectors and locked seeds. Furthermore, it maintains a continuity log tracking the character’s last appearance. Consequently, you generate a coherent narrative assembly efficiently. As a result, your storyboard translates seamlessly into consistent visual sequences. Ultimately, project-level management transforms isolated clips into unified films.
Iterative Refinement and Agent Feedback Loops
Initial generations rarely achieve absolute perfection. Therefore, an iterative refinement process proves absolutely essential. The Invideo agent supports feedback loops where creators reject inadequate frames. When you reject a frame, you provide implicit correction data to the system. The agent adjusts its internal weighting to avoid repeating the specific failure. Furthermore, you can provide explicit text feedback to refine the generation further. This interactive process rapidly converges on your desired visual output. Consequently, you polish your digital actor’s performance with surgical precision. As a result, the final video meets exacting professional standards. Ultimately, human-in-the-loop refinement guarantees superior artistic quality.
Advanced Prompt Engineering for Character Consistency Invideo Agent
Prompting an AI agent differs significantly from prompting a basic image generator. Therefore, elite creators employ advanced linguistic strategies. These techniques communicate intent more clearly to the agent’s understanding modules. Mastering prompt engineering maximizes the consistency and quality of your outputs. Consequently, your text descriptions become powerful directional tools rather than vague suggestions.
Leveraging Negative Prompts to Eliminate Drift
Models sometimes generate unwanted features despite clear instructions. Therefore, negative prompting provides a crucial exclusion mechanism. You explicitly tell the agent what not to include. If your character consistently generates earrings you did not request, add earrings to the negative prompt. The agent aggressively suppresses features listed in this negative space. Furthermore, negative prompts prevent the model from hallucinating accessories during complex scenes. Consequently, you carve away undesired variations, leaving only your precise intent. As a result, your character remains pure and unadulterated by algorithmic hallucinations. Ultimately, negative prompting sharpens the focus of the generative space.
Contextual Anchoring in Scene Descriptions
Scenes do not exist in isolation; they inherit context from previous shots. Therefore, your prompts should reference the ongoing narrative state. Describe what the character is currently doing and feeling. Furthermore, explicitly state their immediate environment and proximity to objects. The Invideo agent utilizes large language models to parse this contextual meaning. It adjusts the character’s posture and expression to match the described scenario logically. Consequently, your digital actor performs contextually appropriate actions rather than generic poses. As a result, your storytelling gains dramatic weight and emotional authenticity. Ultimately, contextual anchoring breathes believable life into digital humans.
Utilizing Emotional Modifiers for Dynamic Performances
Consistency does not mean monotony. Therefore, your character must express diverse emotions while maintaining physical identity. The Invideo agent excels at separating identity from expression. Use strong emotional modifiers in your prompts to drive performance. Instruct the agent to generate a subtle, sad smile or an explosive, angry gesture. The agent applies these emotional deltas on top of the locked identity vector. It ensures the facial muscles move realistically without altering the underlying bone structure. Consequently, your character delivers compelling dramatic performances safely. As a result, your video maintains emotional resonance alongside visual stability. Ultimately, emotional modifiers unlock true acting potential in digital avatars.
The Future of AI Video Editing and Digital Humans
Artificial intelligence video technology evolves at a blistering pace. Therefore, current consistency solutions will only improve exponentially. Future iterations of the Invideo agent will likely incorporate real-time interactive capabilities. Creators will direct digital actors using natural voice commands instantly. Furthermore, lip synchronization algorithms will achieve absolute phonetic perfection. These advancements will erase the final boundaries between digital and biological actors. Consequently, independent creators will produce Hollywood-quality films with minimal budgets.
Real-Time Interactive Character Modification
Waiting for renders tests creative patience severely. Therefore, future agents will likely offer real-time generation interfaces. You will adjust lighting or emotional expression via intuitive sliders. The character will respond instantly, maintaining absolute consistency throughout the modification. This interactive paradigm accelerates the creative cycle dramatically. Furthermore, it allows for spontaneous exploration during live direction sessions. Consequently, directing an AI actor will mirror directing a human performer in a studio. As a result, artistic intuition flows unhindered by technical latency. Ultimately, real-time feedback loops redefine digital content creation.
Emotional Resonance and Lip Sync Precision
Current lip synchronization sometimes exhibits uncanny artifacts. Therefore, future models will map phonemes with sub-millimeter accuracy. The Invideo agent will perfectly match generated mouth shapes to uploaded dialogue audio. Furthermore, it will synchronize micro-expressions like eyebrow raises to vocal inflection. This deep emotional coupling creates astonishingly believable performances. Consequently, viewers will struggle to distinguish AI actors from real humans. As a result, the uncanny valley will finally become a relic of the past. Ultimately, perfect synchronization unlocks limitless applications in entertainment and education.
Conclusion
Producing professional video content requires unwavering visual stability. Therefore, traditional generative methods fail spectacularly at storytelling. However, the character consistency Invideo agent resolves this critical limitation permanently. By leveraging advanced identity anchoring and robust reference images, you lock your digital actors firmly. Furthermore, precise prompt engineering and iterative refinement polish your results to broadcast standards. Ultimately, this powerful platform transforms chaotic AI generation into a reliable, scalable production studio. Implement these tactical workflows today, and produce flawless, cohesive video narratives effortlessly.
Frequently Asked Questions (FAQs)
1. What is the Invideo agent?
The Invideo agent is an advanced AI video generation platform that uses intelligent algorithms to produce and manage consistent digital characters across multiple scenes.
2. Why is character consistency difficult in AI video?
Standard generative models treat each prompt independently, causing random variations in facial features, clothing, and styling between different generated shots.
3. How does the agent maintain facial consistency?
It uses facial landmark detection to map specific geometric points on the face, enforcing these immutable anchors during the diffusion generation process.
4. Can the character change expressions safely?
Yes, the agent separates identity from expression, allowing emotional modifiers to alter facial muscles without changing the underlying bone structure or identity.
5. What role do reference images play?
High-quality reference images provide the baseline visual data that the agent extracts to build the persistent feature vector for your specific character.
6. Does locked seed value improve consistency?
Yes, locking the seed value forces the generative model to start from the same latent noise pattern, significantly enhancing reproducibility across different clips.

Written by Twastia Editorial Team
Twastia Editorial Team shares practical insights about website design, SEO services, Google Ads, content marketing, social media, conversion rate optimization, and digital marketing strategy.
Last updated: Aug 4, 2026
Related posts from Twastia
Explore more useful articles from twastia.com about digital marketing, SEO, websites, ads, content, and growth strategy.